- Домашняя страница /
- Книги /
- Компьютеры и технологии /
- Информатика /
- AI & Machine Learning /
- Intelligence & Semantics /
- Reinforcement Learning from Human Feedback: L...
0 ratings


товар №:
248983336
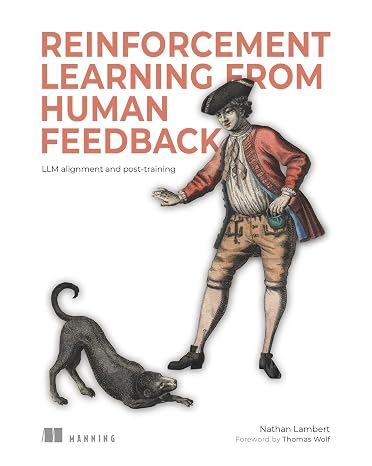
Reinforcement Learning from Human Feedback: LLM alignment and post-training
89% of respondents would recommend this to a friend
товар №:
248983336
KGS 7194
Price Details
Excluding Shipping & Custom charges ( Shipping and custom charges will be calculated on checkout )
*All items will import from США
0 ratings
Написать отзыв
В наличии
 Импортировано из магазина USA
QTY:
Закажите сейчас и получите товар приблизительно Вторник, Октябрь 20
Secured transaction
Ubuy works hard to protect your security and privacy. Our advanced payment security system ensures confidentiality by encrypting your information during transmission using AES (Advanced Encryption Standards) and SSL (Secure Socket Layer) protocols. Your payment details are 100% secure as we do not share your payment details with third party sellers.
Our Top Logistics Partners


Fast
Shipping

Free
Return*

Secure Packaging

100% Original Products

PCI DSS Compliance

ISO 27001 Certified
Note: Step Down Voltage Transformer required for using electronics products of США store (110-120). Recommended power converters Купите сейчас.


Информация о продукте
- Get the eBook free when you register your print book at Manning.A masterful synthesis of the field’s intellectual roots and its practical tools.”—Saurabh Sawant, MicrosoftReinforcement Learning from Human Feedback: LLM alignment and post-training helps you understand how modern AI models can be adapted to better match the needs and expectations of their users. Rather than surveying the vast field of reinforcement learning, elite AI researcher Nathan Lambert concentrates exclusively on RLHF and its immediate importance to post-training generative AI models.This compact book gets right to the point. Early chapters establish the training overview, explain instruction fine-tuning, and build reliable reward models. The middle chapters transition into the heart of alignment, exploring core policy gradient algorithms, Direct Preference Optimization (DPO), and inference-time scaling. Later chapters tackle the messy reality of data, guiding you through preference data collection, synthetic data generation, and the nuances of function calling.As you go, you will see how these post-training methods actually work, including their unique compute costs and latency trade-offs. You will explore common failure modes, such as qualitative over-optimization, reward hacking, and the unreliability of external evaluation comparisons. Difficult concepts like KL regularization, proximal policy optimization, and generative reward modeling are clarified with hands-on experiments.Reinforcement Learning from Human Feedback avoids irrelevant academic details in favor of immediate, practical value. Everything author Nathan Lambert includes appears because a modern RLHF project requires it. He skillfully explains complex post-training pipelines by making every detail concrete, connecting isolated abstractions directly to the goal of making models safer, smarter, and perfectly tuned to a desired style.The book’s seventeen short chapters lay out the core material, while supplements like vocabulary definitions, compute cost management, evaluation variance, and training performance tracking appear in handy appendixes. The result is a logically flowing book that remains highly navigable and technically deep without getting bogged down in unnecessary theory.The book covers• Core RLHF implementations and Direct Alignment Algorithms• Building robust preference and synthetic data pipelines• Evaluating models and crafting specific AI personasAbout the readerFor established engineers, AI scientists, and students trying to get a practical foothold in AI model alignment.About the authorDr. Nathan Lambert is a leading AI researcher known for leading post-training at the Allen Institute for AI. With previous experience at HuggingFace, DeepMind, and Meta, he is a passionate advocate for open models. His work focuses on increasing access to, and the understanding of, AI technology—empowering readers to contribute to the advancement of AI outside closed corporate labs.Table of ContentsPart 11 Introduction2 A tiny history of RLHF3 Training overviewPart 24 Instruction fine-tuning5 Reward modeling6 Reinforcement learning7 Reasoning and inference-time scaling8 Direct-alignment algorithms9 Rejection samplingPart 310 The nature of preferences11 Preference data12 Synthetic dataPart 413 Tool use and function calling14 Over-optimization15 Regularization16 Evaluation17 Crafting model character and productsA DefinitionsB Beyond “just style”C Practical Issues
| Publisher | Manning Publications |
| Publication date | August 4, 2026 |
| Language | English |
| Print length | 312 pages |
| ISBN-10 | 1633434303 |
| ISBN-13 | 978-1633434301 |
| Item Weight | 8.5 ounces (240.98 grams) |
| Dimensions | 7.38 x 0.71 x 9.25 inches (18.7 x 1.8 x 23.5 cm) |
ОПИСАНИЕ ТОВАРА
Reinforcement Learning from Human Feedback: LLM alignment and post-training
Есть вопрос? Пообщайтесь с нами в чате
Вопросы и ответы клиентов
-
вопрос:
Как покупать Reinforcement Learning from Human Feedback: LLM в Интернете на Ubuy?
отвечать: Купить Reinforcement Learning from Human Feedback: LLM онлайн на Ubuy очень просто.. Вам просто нужно найти товар, выбрать способ доставки при оформлении заказа и получить его до вашего места. -
вопрос:
Доступен ли Reinforcement Learning from Human Feedback: LLM для покупок в Интернете в Kyrgyzstan?
отвечать: Да, на Ubuy Kyrgyzstan вы можете купить этот товар по разумной цене.. Reinforcement Learning from Human Feedback: LLM недоступен на месте, но вы можете доверить нам наши услуги экспресс-доставки. -
вопрос:
Сколько времени занимает получение товара после размещения заказа?
отвечать: Время доставки заказанного вами товара зависит от того, что вы заказали, и выбранного вами способа доставки.. Ориентировочное время доставки указывается в процессе оформления заказа, так что будьте беззаботны при совершении покупок.
Intelligence & Semantics Editorial Review
Редакционных отзывов не найдено
Customer Reviews & Ratings
1 оценки клиентов
-
5 звезда
100%
-
4 звезда
0%
-
3 звезда
0%
-
2 звезда
0%
-
1 звезда
0%
Оцените этот товар
Поделитесь своими впечатлениями
Product Price History
Важная информация
- Ограничения: обратите внимание, что для товаров, поставляемых за границу, гарантия производителя может быть недействительной; обслуживание от производителя может быть недоступно; руководства по эксплуатации, а также инструкции и предупреждения о безопасности могут быть не на языках страны назначения; товары (и сопутствующие материалы) могут не быть разработаны в соответствии со стандартами, спецификациями и требованиями к маркировке страны назначения; товары также могут не соответствовать напряжению в стране назначения и другим электрическим стандартам (при необходимости требуется использование адаптера или преобразователя). Получатель несет ответственность за обеспечение законного ввоза товара в страну назначения. При заказе через Ubuy или его аффилированных лиц получатель является зарегистрированным импортером и должен соблюдать все законы и правила страны назначения.
- Не все товары на Ubuy выставлены на продажу, поскольку Ubuy — это глобальная поисковая система. На товары распространяются законы в области экспорта и торговли.
KGS 7194
Закажите сейчас и получите товар приблизительно Вторник, Октябрь 20
This item is not restrict in my country.(Please click on above link if this item is not restrict in your country, So our team will review and allow.)
QTY:
Secured transaction
PCI DSS compliant and ISO 27001:2022 certified, with encrypted payments and full buyer protection on every order.
Our Top Logistics Partners
Fastest cross-border delivery
Ubuy Assurance
Experience worry-free shopping with 100% original products, PCI DSS-compliant payment security, ISO 27001-certified data protection, the fastest cross-border delivery, free returns *, and secure packaging on every order.